AI detector false positive rates, ranked
GPTZero recorded a 0.00% false positive rate on the RAID benchmark's human-written documents at naive threshold 0.5 in Dugan et al. 2024 (arXiv 2405.07940, read 8 November 2026), the lowest figure in the index, and eleven other detectors also posted 0 false positives in at least one independent study. 23 of the 72 detectors in the index have an independently measured rate; eight more publish only a vendor figure. The GPT-2 Output Detector and GLTR joined the ranking on 9 November 2026, and Pangram moved from the vendor table into the ranking the same day on the strength of Jabarian and Imas 2025, which recorded 0.0000 false positives on 1,992 human passages at a 0.5 threshold (NBER w34223, read 9 November 2026). Writer joined the ranking with the third wave of cards on 9 November 2026 at 5.6%, 1 false accusation in 18 human-written documents in Weber-Wulff 2023, the first ranked rate between Scribbr's 2% and GLTR's 99.3%; Undetectable AI joined the vendor table with a 0% figure the vendor attributes to a study not yet indexed. The fourth wave of cards on 9 November 2026 brought three more zeros from Weber-Wulff 2023's 18 human-written documents: DetectGPT, BrandWell (tested as Content at Scale) and Compilatio, whose own "below 1%" on 3,700 human texts goes to the vendor table; TruthScan's "<1%" is an image figure and stays on its card.
Updated Studies dated 2023 to 2026
Short answer
Fifteen of the twenty-three ranked detectors recorded 0 false positives in at least one study; Scribbr, at 2% of 42 papers, Writer, Writefull and Check For AI, each at 1 of 18 documents (5.6%), RADAR, at 3.48% of RAID's human documents at threshold 0.5, SEO.ai, at 12% of 42 papers, and GLTR, at 99.3% of RAID's human documents at threshold 0.5, are the eight above zero (Binoculars, Writefull and Check For AI joined on 10 November 2026, then RADAR and SEO.ai later the same day). The sort value is each tool's lowest published rate; the per-tool blocks list every other rate with its base, because one tool can post 0 of 18 in one paper and 9 of 18 in another. Proofademic and Codequiry publish only vendor-measured rates and sit in a separate table, unranked, joined on 9 November 2026 by Undetectable AI and, with the fourth wave the same day, by Compilatio, whose study zero is ranked and whose vendor rate is tabled. Sources read 8 and 9 November 2026. No detector score should be the only evidence in a misconduct or hiring decision.
Which AI detectors publish the lowest false positive rate?
| Rank | Detector | Lowest published rate | Source and base | Best for | Main limitation |
|---|---|---|---|---|---|
| 1 |  GPTZero | 0% | RAID 2024, human documents at threshold 0.5 | Weighing eleven studies | 9 of 18 false accusations, Weber-Wulff 2023; 52 of 114, Orenstrakh 2023 |
| 2 |  GPT-2 Output Detector | 0% | Perkins 2024, 0 of 10 human samples | A free, open baseline | 0.9503 of 1,992 passages at threshold 0.5 (RoBERTa-base), Jabarian and Imas 2025; 2 of 18, Weber-Wulff 2023 |
| 3 |  Copyleaks | 0% | Walters 2023, 0 of 42 human papers | LMS schools | 5 of 10 false accusations, Perkins 2024 |
| 4 |  Originality.ai | 0% | Walters 2023, 0 of 42 (2 uncertain) | Publishers | 0.25% at threshold 0.5, RAID 2024; 7 of 114, Orenstrakh 2023 |
| 5 |  ZeroGPT | 0% | Weber-Wulff 2023, 0 of 18 human documents | Free monthly checking | 1.42% at threshold 0.5, RAID 2024 |
| 6 |  Turnitin | 0% | Walters 2023, 0 of 42 human papers | Licensed institutions | 88 of 104 AI samples missed, Perkins 2024 |
| 7 | DetectGPT | 0% | Weber-Wulff 2023, 0 of 18 human-written documents through the public demo | Readers who want a zero-shot method's human-text record | Krishna 2023 and Sadasivan 2023 fixed the false positive rate at 1% by threshold rather than measuring it; the demo is gone |
| 8 |  Pangram | 0% | Jabarian and Imas 2025, 0.0000 of 1,992 human passages at threshold 0.5 | Readers who want a 2025 result on a large sample | 0.0075 on restaurant reviews at a Youden threshold, Jabarian and Imas 2025 |
| 9 |  BrandWell | 0% | Weber-Wulff 2023, 0 of 18 human-written documents, tested as Content at Scale | Reading a zero that came with 36 of 36 AI texts missed | 10% of 42 human papers called AI, Walters 2023; the authors call the tool biased towards human classification |
| 10 |  Sapling | 0% | Walters 2023, 0 of 42 (31% uncertain) | Developers wanting an API | 31% of human papers uncertain |
| 11 |  Binoculars | 0% | RAID 2024, 0.00% of human-written documents at threshold 0.5 (0.07% at 0.25), Table 4, repository defaults | Researchers who want a zero printed at four thresholds on 14,971 human documents | 5.40% of human student essays flagged at the default threshold in DAMAGE 2025, essay count not printed; 0.6 accuracy under a repetition penalty in RAID |
| 12 |  GPTKit | 0% | Orenstrakh 2023, 0 of 114 human-written English computing submissions, Table 8 | Readers who weigh a false accusation above a miss | 4.5% accuracy on AI text after manipulation, Perkins 2024; 0 of 10 human samples in the same study |
| 13 |  Winston AI | 0% | Weber-Wulff 2023, 0 of 18 human documents | Text plus image checks | 0.55% at threshold 0.5, RAID 2024 |
| 14 |  Compilatio | 0% | Weber-Wulff 2023, 0 of 18 human-written documents | Institutions pairing a study zero with a vendor rate | The vendor's own below 1% on 3,700 human texts is a vendor figure; one study record |
| 15 |  PlagiarismCheck | 0% | Weber-Wulff 2023, 0 of 18 human-written documents, Table 9 | LMS institutions weighing the suite's detector | 19 of 36 AI documents undetected and rank 13 of 14 in the same study; the vendor knew the documents were a test suite |
| 16 |  Scribbr | 2% | Walters 2023, 42 human papers, 2% flagged | Unlimited free checks | 1 study; 2% of 42 is 1 paper |
| 17 |  RADAR | 3.48% | RAID 2024, 3.48% of human-written documents at threshold 0.5 (7.48% at 0.25, 1.23% at 0.95), Table 4, queried from Hugging Face | Researchers who want an open adversarially trained method's printed rate at four thresholds | 51.87% of human student essays flagged at the default threshold in DAMAGE 2025, essay count not printed; 20.4% on reviews at RAID's 5% operating point |
| 18 |  Writer | 5.60% | Weber-Wulff 2023, 1 of 18 human-written documents | Reading what the 2023 studies found for a withdrawn tool | 14% of 42 human papers, Walters 2023; 2 of 5 human paragraphs rated Likely AI-Generated, Elkhatat 2023; tool withdrawn 22 December 2025 |
| 19 |  Writefull | 5.60% | Weber-Wulff 2023, 1 of 18 human-written documents, Table 9 | Readers who want the one printed count for a discontinued tool | 18 of 36 AI documents undetected in the same study; the tool is discontinued |
| 20 |  Check For AI | 5.60% | Weber-Wulff 2023, 1 of 18 human-written documents, Table 9 | Readers who want the one printed count for a tool sunset in 2023 | 12 of 36 AI documents undetected in the same study; sunset notice since July 2023 |
| 21 |  SEO.ai | 12% | Walters 2023, 12% of 42 human-written papers called AI, Table 4 | Readers who want the one printed rate for a free no-login tool | The third-highest false positive rate of 16 in the study; 24% of 126 documents returned as uncertain |
| 22 | Fast-DetectGPT | 23.20% | RAID 2024, human-written documents at threshold 0.5 (47.3% at 0.25, 1.70% at 0.95), Table 4 | Researchers who want the rate at a stated threshold on 14,971 human documents | A naive threshold the authors did not tune; the detector plateaus at 0.88% as its lowest reachable false positive rate |
| 23 | 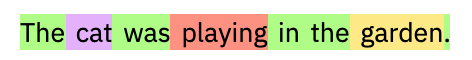 GLTR | 99.30% | RAID 2024, human documents at threshold 0.5 | Seeing the evidence word by word | 100% at threshold 0.25; 0.05% at 0.95, RAID 2024; 20 of 114, Orenstrakh 2023 |
Rates stated by the vendor
Pangram's vendor figure, 0.01% (1 in 10,000) on an aggregate of public datasets containing tens of millions of written documents (pangram.com, read 8 November 2026), sat in this table until 9 November 2026, when the Jabarian and Imas 2025 record gave the card a study-sourced rate and moved it into the ranking above.
| Detector | Vendor-stated rate | Base, in the vendor's words | Source |
|---|---|---|---|
| Proofademic | 0.2% | 4,200 fully human-authored academic texts, March 2026 evaluation | proofademic.ai, read 8 November 2026 |
| Codequiry | 1.3% (code) | Human-written code falsely flagged by model v3e; no sample size published | codequiry.com, read 9 November 2026 |
| Undetectable AI | 0% | "100% detection / 0% false positives", the vendor's summary of a study of ten free detectors in the Indian Journal of Psychological Medicine, in the comparison table on the detector page; no base stated on the page | undetectable.ai/ai-detector, read 9 November 2026 |
| Compilatio | below 1% | "out of 100 passages identified as written by a human, fewer than 1 are incorrectly identified as generated by AI", on 3,700 human texts in 24 languages, model 4.5.3; the card's ranked 0% is the Weber-Wulff 2023 study figure | support.compilatio.net, read 9 November 2026 |
| PlagiarismCheck | 1.04% (sentences); 0.00% (documents) | 280,781 human-written sentences and 2,805 human documents at the over-50% threshold, in a benchmark post of July 2026 the detector page calls marketing figures; the card's ranked 0% is the Weber-Wulff 2023 study figure | plagiarismcheck.org/ai-detector, read 9 November 2026 |
| Isgen | "nearly 0%" | "a false positive ratio of nearly 0%" on the home page; no base, count or dataset stated | isgen.ai, read 9 November 2026 |
| Detecting-AI.com | under 1% | "<1% False positive rate" and "keeping wrong flags on human writing under 1% in Detecting AI's published benchmarks"; no base, count or dataset stated, so the bound is not ranked (the TruthScan treatment) | detecting-ai.com, read 10 November 2026 |
| Ircam Amplify | under 1% (music); 0.14% at the 50% threshold | "Less than 1% false positives" on the home page; the V2.3 release note prints 0.14% at the 50% threshold and 0.02% at the 80% threshold "on Ircam Amplify's internal benchmark datasets", with no dataset size or composition published, so the bound is not ranked (the TruthScan treatment) | ircamamplify.com, read 10 November 2026 |
No sort value moved in the sixth wave on 9 November 2026, and the rule that decides that is stated here: the field takes the lowest study-sourced rate printed on human-written text, and where two rates are equal the card keeps the one with the larger base, with ties in the table broken by study records and then name. Epoch AI 2026 printed 0 of 495 pre-2022 human passages for Pangram and GPTZero and 19 of 495 (3.84%) for Originality.ai; Pangram already holds 0 of 1,992 from Jabarian and Imas 2025 and GPTZero 0.00% on RAID's human documents, so the Epoch figures were added to each card's base text, and Originality.ai's 3.84% is not lower than its 0 of 42. Ibrahim 2023 prints 16 of 120 human ESL essays below a 95% originality cut under the author's inverted label "false negatives", a figure kept in prose on the GPT-2 Output Detector card and not entered as a rate. The GPTZero and Pangram vendor benchmarks (0.08% and 70 of 781,981) are vendor measurements and sit in the vendor benchmarks record, never in this table.
One of ten rankings in the rankings hub, beside independently tested detectors and free tiers. The home board answers which AI detectors exist and who has tested them?
Which AI detectors should you check first?
- GPTZero, rank 1Best for: Weighing eleven studies. Main limitation: 9 of 18 false accusations, Weber-Wulff 2023; 52 of 114, Orenstrakh 2023.
- GPT-2 Output Detector, rank 2Best for: A free, open baseline. Main limitation: 0.9503 of 1,992 passages at threshold 0.5 (RoBERTa-base), Jabarian and Imas 2025; 2 of 18, Weber-Wulff 2023.
- Copyleaks, rank 3Best for: LMS schools. Main limitation: 5 of 10 false accusations, Perkins 2024.
- Originality.ai, rank 4Best for: Publishers. Main limitation: 0.25% at threshold 0.5, RAID 2024; 7 of 114, Orenstrakh 2023.
- ZeroGPT, rank 5Best for: Free monthly checking. Main limitation: 1.42% at threshold 0.5, RAID 2024.
What does each study report for each tool?
GPTZero
- Verdict
- Fits readers weighing six disagreeing studies.
- Value
- 0.00% at threshold 0.5 on human-written documents, 0.03% at 0.25, RAID 2024, read 8 November 2026.
- Best for
- Educators who read every result.
- Main limitation
- 9 false accusations in 18 human documents, 6 on machine-translated texts, highest of 14 tools, Weber-Wulff 2023; also 2% of 42 in Walters 2023, 1 of 10 in Perkins 2024, 1 of 5 in Elkhatat 2023, read 8 November 2026; 52 of 114 human coursework submissions in Orenstrakh 2023, 0.0071 of 1,992 passages at every fixed threshold in Jabarian and Imas 2025 and 0 of 40 papers in Van Vlasselaer 2026, read 9 November 2026.
ZeroGPT
- Verdict
- Fits free users; zero in two small samples.
- Value
- 0 false accusations in 18 human-written documents, Weber-Wulff 2023, read 8 November 2026.
- Best for
- Students on the free monthly allowance.
- Main limitation
- 1.42% at threshold 0.5 and 1.71% at 0.25, the highest RAID rates among index cards, RAID 2024; also 0 of 10 in Perkins 2024 and 2% of 42 in Walters 2023, read 8 November 2026.
GPT-2 Output Detector
- Verdict
- Fits readers who want a free, open baseline; zero in one small sample.
- Value
- 0 false accusations in 10 human samples, Perkins 2024, read 9 November 2026. Added to the base on 10 November 2026: Rashidi 2023 ran the same RoBERTa-base weights on 14,400 real journal abstracts and printed up to 8.69% of a 1,600-abstract five-year range above a 50% score and 10.24% of NEJM abstracts above 90% (DOI 10.1016/j.jpi.2023.100342, read 10 November 2026); the field keeps the lowest study value under the ranking rule.
- Best for
- Researchers running the model locally at no cost.
- Main limitation
- 2 false accusations in 18 human documents, both machine-translated, Weber-Wulff 2023; 2.91% (large) and 6.59% (base) at threshold 0.5 in RAID 2024, read 9 November 2026; 0.9503 of 1,992 human passages at threshold 0.5 for the RoBERTa-base baseline in Jabarian and Imas 2025, 2 of 114 in Orenstrakh 2023 and specificity 94% on 50 abstracts in Gao 2023, read 9 November 2026.
Turnitin
- Verdict
- For institutions licensing Turnitin Originality.
- Value
- 0 of 42 human papers flagged as AI, Walters 2023, read 8 November 2026.
- Best for
- Universities that fear false accusations most.
- Main limitation
- 88 of 104 AI samples undetected, 0 of 10 human samples flagged, Perkins 2024; also 0 of 18 in Weber-Wulff 2023; read 8 November 2026.
Copyleaks
- Verdict
- Fits LMS schools accepting conflicting results.
- Value
- 0 of 42 human papers flagged as AI, Walters 2023, read 8 November 2026.
- Best for
- Schools that also want AI text caught.
- Main limitation
- 5 false accusations in 10 human samples, the highest of seven tools, Perkins 2024; also 1 of 5 in Elkhatat 2023; read 8 November 2026.
Originality.ai
- Verdict
- Fits publishers; a zero plus a benchmark figure.
- Value
- 0 of 42 human papers flagged as AI, 2 uncertain, Walters 2023, read 8 November 2026.
- Best for
- Content teams scanning long-form articles.
- Main limitation
- 0.25% at threshold 0.5 and 0.47% at 0.25, RAID 2024, read 8 November 2026; the Walters test ran detection model 1.4, since replaced.
Pangram
- Verdict
- Fits readers who want a 2025 rate on a large human sample.
- Value
- 0.0000 of 1,992 human passages at a 0.5 threshold on the API's prob_ai field, Jabarian and Imas 2025 Table 3, read 9 November 2026; also 0 of 40 human papers in Van Vlasselaer 2026.
- Best for
- Readers checking pre-2020 prose genres: reviews, blogs, news, fiction, resumes.
- Main limitation
- 0.0010 at the 0.1 threshold and up to 0.0075 on restaurant reviews at a Youden-optimised threshold in the same paper; the vendor's own 1 in 10,000 figure (pangram.com, read 8 November 2026) rests on vendor-chosen data.
Sapling
- Verdict
- Fits developers who accept uncertain results.
- Value
- 0 of 42 human papers flagged as AI, Walters 2023, read 8 November 2026.
- Best for
- Teams treating uncertain as no result.
- Main limitation
- 31% of the 42 human papers returned uncertain, so only 69% were classified as human, Walters 2023, read 8 November 2026.
Winston AI
- Verdict
- Fits users checking text and images in one account.
- Value
- 0 false accusations in 18 human-written documents, Weber-Wulff 2023, read 8 November 2026.
- Best for
- Writers on a credit plan.
- Main limitation
- 0.55% at threshold 0.5 and 0.75% at 0.25, RAID 2024, read 8 November 2026; the vendor's own zero across 27,743 documents is a vendor statement (gowinston.ai).
Scribbr
- Verdict
- Fits students wanting unlimited free checks.
- Value
- 2% of 42 human papers flagged as AI, Walters 2023, read 8 November 2026.
- Best for
- Students checking drafts.
- Main limitation
- Walters 2023 is the only study record, and 2% of 42 papers is 1 paper (Walters 2023, read 8 November 2026).
Writer
- Verdict
- Fits readers tracing the 2023 record of a detector that was withdrawn on 22 December 2025.
- Value
- 1 false accusation in 18 human-written documents (5.6%), on a machine-translated text, Weber-Wulff 2023, read 9 November 2026.
- Best for
- Readers who meet Writer in a 2023 paper and want its rate beside the tools still sold.
- Main limitation
- 14% of 42 human-written papers called AI, tied with Crossplag for the highest false positive rate of 16 detectors, Walters 2023; 2 of 5 human paragraphs rated Likely AI-Generated and 1 Uncertain, Elkhatat 2023, both read 9 November 2026; the tool and its API were sunset on 22 December 2025 (archived detector page, read 9 November 2026), so no later rate can exist.
GLTR
- Verdict
- Fits readers who want to see the evidence word by word, at the default threshold a near-certain false flag.
- Value
- 99.3% of RAID's human-written documents at threshold 0.5, RAID 2024, read 9 November 2026.
- Best for
- Teaching what a detector reads; the tool colours every word by rank.
- Main limitation
- 100% at threshold 0.25 and 21.0% at 0.75 in the same paper; the rate falls to 0.05% only at 0.95 (RAID 2024, read 9 November 2026); 20 of 114 human coursework submissions through the authors' z-score wrapper in Orenstrakh 2023, read 9 November 2026.
DetectGPT
- Verdict
- Fits readers who want a human-text zero from a method with no trained classifier.
- Value
- 0%: 0 false accusations in 18 human-written documents, Weber-Wulff 2023 Table 9, tested through the public demo in March 2023 (read 9 November 2026).
- Best for
- Researchers reading the 2023 record of zero-shot detection.
- Main limitation
- Krishna 2023 and Sadasivan 2023 set the false positive rate to 1% by choosing the threshold on human text, so neither measured it; the hosted demo returned 404 on 9 November 2026.
BrandWell
- Verdict
- Fits readers who want to see how a zero false positive rate can sit beside a zero detection rate.
- Value
- 0%: 0 false accusations in 18 human-written documents, Weber-Wulff 2023 Table 9, tested as Content at Scale (read 9 November 2026).
- Best for
- Readers weighing a zero against the same study's 36 of 36 AI documents undetected.
- Main limitation
- Walters 2023 recorded 10% of 42 human papers called AI for the same tool, and Weber-Wulff's authors write that it is biased towards human classification; the detector page now redirects to a Moxby Mod.
Compilatio
- Verdict
- Fits institutions that want a study zero and a vendor rate for the same tool side by side.
- Value
- 0%: 0 false accusations in 18 human-written documents, Weber-Wulff 2023 Table 9 (read 9 November 2026).
- Best for
- Procurement readers comparing Compilatio with Turnitin on one study.
- Main limitation
- The vendor's own rate, below 1% on 3,700 human texts for model 4.5.3, sits in the vendor column and never enters the sort (support.compilatio.net, read 9 November 2026); one study record.
GPTKit
- Verdict
- Fits readers who want the one detector of eight at zero on 114 real student submissions.
- Value
- 0 of 114 human-written English computing submissions flagged, the only detector of eight at zero, by the paper's threshold method (arXiv 2307.07411, Table 8, read 9 November 2026); also 0 false accusations in 10 human samples in Perkins 2024 (Table 10).
- Best for
- Readers for whom a wrong accusation costs more than a missed text.
- Main limitation
- The same paper scored 75.00% on 20 ChatGPT submissions and 30% on 10 after a QuillBot paraphrase (Tables 6 and 9), and Perkins 2024 recorded 4.5% mean accuracy on AI text after adversarial techniques, the lowest of seven (DOI 10.1186/s41239-024-00487-w, Table 8, read 9 November 2026).
PlagiarismCheck
- Verdict
- Fits readers who want the zero read beside the 13th-of-14 accuracy from the same spring.
- Value
- 0 false accusations in 18 human-written documents, 9 of them machine-translated, tested 2 to 8 May 2023 (arXiv 2306.15666, Table 9, read 9 November 2026). Vendor-stated rates, not ranked: 1.04% of 280,781 human sentences and 0.00% of 2,805 human documents at the over-50% threshold in a benchmark post of July 2026 (plagiarismcheck.org/ai-detector, read 9 November 2026).
- Best for
- Canvas, Moodle, Blackboard, Brightspace, Schoology or Google Classroom institutions already on the plagiarism suite.
- Main limitation
- 19 of 36 AI documents undetected (52.8%, Table 10) and 21 of 54 documents correct overall (rank 13 of 14, Table 5); the authors note the vendor knew the documents were a test suite (arXiv 2306.15666, read 9 November 2026).
Fast-DetectGPT
- Verdict
- Fits researchers who want a false positive rate printed at four thresholds on one large human set.
- Value
- 23.2% of RAID human-written documents flagged at threshold 0.5, run as F-DetectGPT with the repository defaults; 47.3% at 0.25, 13.1% at 0.75 and 1.70% at 0.95 (arXiv 2405.07940, Table 4, read 10 November 2026). The GLTR treatment: a repository-default rate on the human set, entered as printed.
- Best for
- Readers who want to see how an open zero-shot method trades false positives against threshold.
- Main limitation
- The 0.5 threshold is the paper's naive setting, not one the authors tuned; the detector plateaus at 0.88% as the lowest false positive rate it can reach (Finding 2), and accuracy falls to 0.6 on open non-chat models under sampling with a repetition penalty (Table 5), all in RAID 2024, read 10 November 2026.
Binoculars
- Verdict
- Fits researchers who want a zero on a large human set with the thresholds printed.
- Value
- 0.00% of RAID human-written documents flagged at threshold 0.5, 0.07% at 0.25 and 0.00% at 0.75 and 0.95, run from the official repository with the default Falcon-7B pair (arXiv 2405.07940, Table 4, read 10 November 2026); the GLTR and Fast-DetectGPT treatment of a repository-default rate.
- Best for
- Readers who weigh a false accusation first and can run the code themselves.
- Main limitation
- DAMAGE 2025 prints 5.40% of human student essays flagged at the tool's default threshold, with the essay count not printed, so that figure sits in the base and not the field (arXiv 2501.03437, Table 7, read 10 November 2026); RAID's accuracy falls to 0.6 under sampling with a repetition penalty (Table 5).
Writefull
- Verdict
- Fits readers who want the printed count beside the discontinuation notice.
- Value
- 1 false accusation in 18 human-written documents, 9 of them machine-translated, tested 7 to 28 March 2023 (arXiv 2306.15666, Table 9, read 10 November 2026); Pegoraro 2023 prints a 99.3% true negative rate on human responses with no count (arXiv 2304.01487, Table I).
- Best for
- Readers reading a 2023 Writefull percentage.
- Main limitation
- 18 of 36 AI documents undetected (50.0%, Table 10) and 23 of 54 correct overall (rank 12 of 14, Table 5); the vendor discontinued the tool before 7 March 2025 (web.archive.org, 31 December 2024, read 10 November 2026).
Check For AI
- Verdict
- Fits readers who want the printed count for a free tool that closed the same summer.
- Value
- 1 false accusation in 18 human-written documents, 9 of them machine-translated, tested 7 to 28 March 2023 (arXiv 2306.15666, Table 9, read 10 November 2026).
- Best for
- Readers reading a March 2023 Check For AI risk score.
- Main limitation
- 12 of 36 AI documents undetected (33.3%, Table 10) and 32 of 54 correct overall (rank 6 of 14, Table 5); the sunset notice has stood since the capture of 23 July 2023 (web.archive.org, 27 May 2023, read 10 November 2026).
RADAR
- Verdict
- Fits researchers who want a printed rate on a large human set beside a default-threshold collapse.
- Value
- 3.48% of RAID human-written documents flagged at threshold 0.5, 7.48% at 0.25, 2.17% at 0.75 and 1.23% at 0.95, queried from Hugging Face as TrustSafeAI/RADAR-Vicuna-7B (arXiv 2405.07940, Table 4, read 10 November 2026); the GLTR, Fast-DetectGPT and Binoculars treatment of a repository-default rate.
- Best for
- Readers who weigh a false accusation first and can run the model themselves.
- Main limitation
- DAMAGE 2025 prints 51.87% of human student essays flagged at the tool's default threshold, with the essay count not printed, so that figure sits in the base and not the field (arXiv 2501.03437, Table 7, read 10 November 2026); at RAID's 5% total operating point the per-domain rate ran from 0.1% on recipes to 20.4% on reviews (Table 8).
SEO.ai
- Verdict
- Fits readers who want the printed rate beside a 98.4% claim.
- Value
- 12% of the 42 human-written papers called AI, the third-highest false positive rate of the 16 detectors after Crossplag and Writer at 14%, tested June 25 to July 12, 2023 (DOI 10.1515/opis-2022-0158, Table 4, read 8 November 2026).
- Best for
- Readers reading a free SEO.ai score on their own writing.
- Main limitation
- 72% of 126 documents correct overall with 24% uncertain (Table 4); the detector page claims 98.4% with no dataset (seo.ai/tools/ai-content-detector, read 10 November 2026).
How we ranked
- Field sorted
- Lowest published rate on human-written text from an indexed study, sample size shown
- Direction
- Lower first
- Tie rule
- Larger sample size
- Qualification
- A study reporting the rate
- Qualified
- 23 of 72 detectors
Field sorted: the published false positive rate on each card, from the independent study reporting the lowest rate for that detector, compiled on 9 November 2026. Direction: lower ranks higher. Tie rule: twelve tools tie at 0, so ties break on study records per card, most first, then product name alphabetically (GPTZero 12, the GPT-2 Output Detector 10, Copyleaks 7; Originality.ai and ZeroGPT 6 each; Turnitin 5; DetectGPT 4; BrandWell 3; Pangram, Sapling and Winston AI 2 each; Compilatio 1, counts as of the fifth wave on 9 November 2026, when Pegoraro 2023 lifted nine of them and moved ZeroGPT above Turnitin). Qualification rule: a rate from an independent study in the index; vendor-stated rates sit in a separate table, unranked, and cards with no published rate are omitted. 23 of 72 qualified; the GPT-2 Output Detector and GLTR were added on 9 November 2026, Pangram moved into the ranking later the same day when the Jabarian and Imas 2025 record was indexed, and Writer joined at 5.6% with the third wave of cards the same day; DetectGPT, BrandWell and Compilatio joined at 0 from Weber-Wulff 2023 with the fourth wave. TruthScan publishes a "False positive rate <1%" for image detection with no base, an image figure kept off this text-only field and carried on the TruthScan card. Hive's 0% on 280 human artworks (Ha and Passananti 2024) is an image result and is listed in the false negative rate ranking and the annual false positive evidence review, not here, because this page sorts rates on human-written text; AI or Not's 24.47% on the same 280 artworks, measured under the name Optic in the same paper, is kept off this page by the same rule and sits on the AI or Not card. Full rules: methodology page; each paper: studies index. The published false positive rate view lists every card with a figure of either kind in one table, and the question on vendor claims under 1% sets each vendor's claim beside the studies that checked it.
Why numbers differ between sources
The false positive studies question, added 9 November 2026, counts how many records stand behind each figure here: GPTZero's lowest rate is one of 11 human-text figures across its records, Scribbr's and Compilatio's one of one.
A rate depends on the texts, the threshold and the date. Weber-Wulff 2023 used 18 documents, 9 machine-translated, where 6 of GPTZero's 9 false accusations fell (arXiv 2306.15666). Walters 2023 allowed an uncertain verdict, which is why Sapling shows 0 false positives with 31% uncertain (DOI 10.1515/opis-2022-0158). RAID 2024 reports four rates per tool at thresholds 0.25 to 0.95 (arXiv 2405.07940). Copyleaks publishes 0.03% on the product page and 0.30% on the methodology page (copyleaks.com). All read 8 November 2026. Jabarian and Imas 2025 fixed thresholds on each API's own probability field, which is why GPTZero's 0.0071 holds at every threshold while Pangram's falls from 0.0010 to 0.0000 (NBER w34223, read 9 November 2026); Orenstrakh 2023 counted a false positive at a 50% probability on the authors' scale (arXiv 2307.07411, read 9 November 2026).
Questions about AI detector false positive rates
Which AI detector has the lowest false positive rate?
Twelve detectors share the lowest published figure, 0 false positives in at least one study: GPTZero, the GPT-2 Output Detector, Copyleaks, Originality.ai, Turnitin, ZeroGPT, DetectGPT, BrandWell, Pangram, Sapling, Winston AI and Compilatio. GPTZero ranks first because the 0.00% comes from RAID 2024, the largest benchmark indexed. Sources read 8 November 2026.
Why is GPTZero ranked first with a 50% result in another study?
The sort value is the lowest published rate, 0.00% at threshold 0.5 in RAID 2024, and the per-tool block lists the 9 of 18 result from Weber-Wulff 2023 beside that figure. Different texts and thresholds produced the two results. Sources read 8 November 2026.
How big were the human samples behind these rates?
The samples were 18 human-written documents in Weber-Wulff 2023, 42 human papers in Walters 2023, 10 human samples in Perkins 2024 and 5 human controls in Elkhatat 2023. RAID 2024 reports percentages of the benchmark's human-written documents. Sources read 8 November 2026. Rashidi 2023, added on 10 November 2026 to the GPT-2 Output Detector's base, scored 14,400 real journal abstracts, 1,600 per five-year range, the largest human set in the index after RAID's.
What false positive rate does Turnitin report?
Turnitin states under 1% for documents with over 20% AI writing, validated on over 700,000 pre-ChatGPT papers (guides.turnitin.com, read 8 November 2026). Independent studies report 0 of 42, 0 of 18 and 0 of 10.
Why are Proofademic and Codequiry in a separate table?
Proofademic's 0.2% is a vendor-stated rate on data the vendor chose, and no independent study in the index covers the tool. The index ranks only figures an outside study reports, so it sits in its own table. Pangram's 0.01% sat beside it until 9 November 2026, when Jabarian and Imas 2025 gave the card a study-sourced 0.0000 of 1,992. Sources read 8 November 2026. Codequiry's 1.3% false flag rate on human-written code joined the same table on 9 November 2026 under the same rule, with no sample size published. Undetectable AI's 0% was added to the table on 9 November 2026: the detector page attributes it to a study of ten free detectors in the Indian Journal of Psychological Medicine that the index has not yet read, so the figure is filed as a vendor statement until the paper is indexed. Compilatio's "below 1%" on 3,700 human texts was added to the table on 9 November 2026 with the fourth wave; the card itself is ranked at 0 because Weber-Wulff 2023 measured 0 false accusations in 18 human documents, and the two figures sit on two different pages of this ranking by design.
Does a 0% false positive rate mean a detector never flags human text?
No: 0 of 18 or 0 of 42 means no false positive appeared in that sample on that date. ZeroGPT recorded 0 of 18 in Weber-Wulff 2023 and 1.42% at threshold 0.5 in RAID 2024. Small samples cannot rule out 1 or 2 percent. Sources read 8 November 2026.
Do false positives rise for non-native English writers?
Liang 2023 reports an average false positive rate of 61.22% across seven detectors on 91 TOEFL essays, against near-perfect accuracy on 88 US 8th-grade essays (arXiv 2304.02819, read 8 November 2026). Per-detector rates appear only in a chart.
How often is this ranking updated?
The ranking was created in November 2026 and changes whenever a study record with a false positive figure is added or a vendor figure changes, with the Updated line matching. A vendor rate is ranked only once an independent study covers the tool. Figures from the index, compiled 8 November 2026.
Sources and revisions
Sources
- Dugan et al. 2024, RAIDarxiv.org/pdf/2405.07940
- Weber-Wulff et al. 2023arxiv.org/pdf/2306.15666
- Walters 2023degruyterbrill.com/document/doi/10.1515/o...
- Perkins et al. 2024arxiv.org/pdf/2403.19148
- Elkhatat et al. 2023link.springer.com/content/pdf/10.1007/s40...
- Liang et al. 2023arxiv.org/pdf/2304.02819v3
- Turnitin FAQsguides.turnitin.com/hc/en-us/articles/284...
- Copyleaks methodologycopyleaks.com/ai-detector/testing-methodo...
- Winston AIgowinston.ai
- Pangrampangram.com
- Proofademicproofademic.ai/ai-text-detector
- Codequiry AI code detectioncodequiry.com/detect-ai-written-code
- Jabarian and Imas 2025, NBER w34223nber.org/papers/w34223
- Orenstrakh et al. 2023arxiv.org/abs/2307.07411
- Van Vlasselaer et al. 2026doi.org/10.1007/s40979-026-00226-w
- Gao et al. 2023doi.org/10.1038/s41746-023-00819-6
- Undetectable AI detector pageundetectable.ai/ai-detector
- Writer AI Content Detector, archived 9 December 2025web.archive.org/web/20251209115654/https:...
- Compilatio support article on reliability (read 9 November 2026)support.compilatio.net/hc/en-us/articles/...
- TruthScan pricing page, image false positive figure (read 9 November 2026)truthscan.com/pricing
- BrandWell archived detector page (read 9 November 2026)web.archive.org/web/20260809041054/https:...
- DetectGPT paper (read 9 November 2026)arxiv.org/abs/2301.11305
Revision log
- Ranking created
- Gpt-2 output detector, gltr and the codequiry vendor row added, 10 of 22 qualify
- Copyleaks moved to third on the tie rule after the chaka 2023 record raised its study count to 4
- Pangram moved from the vendor table into the ranking on the jabarian and imas 2025 record, 11 of 22 qualify, order re-sorted on the new study counts
- Six wave 3 cards added, writer joins at 5
- Ten wave 4 cards added, detectgpt, brandwell and compilatio join at 0% from weber-wulff 2023, 15 of 38 qualify
- Four wave 5 cards and two records added
- Eleven wave 6 records added
- False positive studies question linked (seventh wave)
- Nine wave 9 cards added
- Twelve wave 10 cards added
- Nine wave 11 cards added
). Illuminarty, one of four cards added in the same wave, joined with its one image record from Ha and Passananti 2024, so 18 of 72 cards now qualify.: register plate](/img/independently-tested-480.webp)