GLTR AI detector
Vendor Gehrmann, Strobelt and Rush (MIT-IBM Watson AI Lab and HarvardNLP) Official site gltr.io How this card is sourced
Updated · AI Detector Index editors
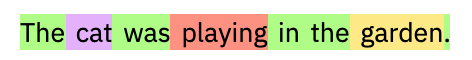
GLTR, the Giant Language Model Test Room, is an open-source tool published in 2019 that colours every word of a text by how highly the GPT-2 117M model ranked that word as the next one, according to the project page at gltr.io read 9 November 2026. The tool has no vendor, no price and no account; the ACL 2019 demo paper by Sebastian Gehrmann, Hendrik Strobelt and Alexander M. Rush stands in for the product page. GLTR is one of twenty-two cards in the full detector index, and how this card is sourced explains why several fields are missing.
What GLTR detects
| Field | Value | Source |
|---|---|---|
| Content types detected | Text | gltr.io |
| Generators covered | GPT-2 (the public demo analyses text with the GPT-2 117M model; the paper validates the method on GPT-2 1.5B samples at temperature 0.7 and top-40 truncation, and on Washington Post Heliograf articles), BERT is offered as an alternative backend model | gltr.io |
| Input limits | Any textual input pasted into the demo; no character or word limit is published. Each word is coloured by its rank under GPT-2 117M: top 10 green, top 100 yellow, top 1,000 red, the rest purple, with three histograms over the whole text. | gltr.io |
| Free tier | Free and open source (Apache License 2.0): public demo at demo.gltr.io with no account, and the server runs locally from the GitHub repository (python server.py) | github.com/HendrikStrobelt/detecting-fake... |
| API | Yes, github.com/HendrikStrobelt/detecting-fake... | github.com/HendrikStrobelt/detecting-fake... |
| Launch year | 2019 | arxiv.org/abs/1906.04043 |
| Ownership | Open-source research project under the Apache License 2.0 by Hendrik Strobelt, Sebastian Gehrmann and Alexander M. Rush, a collaboration of the MIT-IBM Watson AI Lab and HarvardNLP; no company. GitHub repository created April 11, 2019, last pushed January 18, 2024. | github.com/HendrikStrobelt/detecting-fake... |
| Independent studies | 4 records | Studies index |
GLTR analyses text only. The project page states that the demo "has access to the GPT-2 117M language model from OpenAI" and uses it to compute what GPT-2 would have predicted at each position, then overlays a colour on each word by rank: green for the top 10 predictions, yellow for the top 100, red for the top 1,000 and purple for everything else (gltr.io, read 9 November 2026). Three histograms summarise the whole text: the count of words in each colour bucket, the ratio between the top prediction and the actual word, and the entropy of each prediction. A text made mostly of green and yellow words is the signal the authors read as generated.
The GitHub repository adds a BERT backend as an alternative model and publishes the code under the Apache License 2.0; the repository was created on April 11, 2019 and last pushed on January 18, 2024 (GitHub, read 9 November 2026). The paper validated the method on 50 articles each from GPT-2 1.5B and the Washington Post Heliograf system against three human sources (arXiv 1906.04043, read 9 November 2026). No list of supported languages is published; every example is English.
Two cards share GLTR's lineage. The GPT-2 Output Detector is OpenAI's own classifier trained on GPT-2 outputs, and ZeroGPT is a commercial tool that, like GLTR, scores text on how predictable the words are. GLTR differs from both in that the tool shows the reader the evidence word by word rather than returning a single verdict.
Limits and plans
GLTR publishes no character or word limit. The demo at demo.gltr.io accepts any pasted text, and the README's quickstart runs the same server on a local machine with python server.py, which serves the interface and an API on port 5001 (GitHub README, read 9 November 2026). Because the project is free software, there is no plans table.
GLTR publishes no privacy policy, no retention statement and no list of integrations. The project page gives an email contact and the Twitter accounts of the two first authors, and nothing else about how pasted text is handled by the public demo (gltr.io, read 9 November 2026). A reader who wants a retention guarantee can run the server locally, which keeps the text on their own machine.
What the vendor claims
In a human-subjects study, we show that the annotation scheme provided by GLTR improves the human detection-rate of fake text from 54% to 72% without any prior training.
The paper's abstract carries the project's one quantified claim: "In a human-subjects study, we show that the annotation scheme provided by GLTR improves the human detection-rate of fake text from 54% to 72% without any prior training" (arXiv 1906.04043, read 9 November 2026). The study ran 35 volunteer students through five texts without the overlay and five with it; accuracy rose from 54.2% to 72.3%. The paper also reports a cross-validated AUC of 0.87 for a logistic regression on the GPT-2 top-k bucket features, against 0.63 for a bag-of-words baseline (Table 1 of the paper).
The authors publish no false positive rate. Their discussion section states the limits plainly: "Obviously, GLTR is not perfect. Its main limitation is its limited scale. It won't be able to automatically detect large-scale abuse, only individual cases. Moreover, it requires at least an advanced knowledge of the language to know whether an uncommon word does make sense at a position" (gltr.io, read 9 November 2026). On evasion, the same page says the method "assumes a simple sampling scheme" and that adversaries might change sampling parameters per word or sentence.
A GLTR reading is a visual aid for a human judgement, and the authors say so. The method was built for the GPT-2 era, which matters when the text under review came from a 2026 model.
What independent studies found
- AIDI-S-0006RAID 20242024
GLTR (repository default settings): false positive rate on RAID human-written documents of 100% at threshold 0.25, 99.3% at 0.5, 21.0% at 0.75 and 0.05% at 0.95 (Table 4), the highest at 0.5 of the 12 detectors alongside LLMDet at 96.0%; accuracy at 5% FPR of 89.8 on open chat models with greedy decoding and 0.5 on open non-chat models under sampling with a repetition penalty (Table 5); 62.6 with no attack, 31.2 under synonym swap (-31.4) and 24.3 under homoglyphs (-38.3) (Table 6).
- AIDI-S-0009Chaka 20232023
Chaka 2023: GLTR classified 1 of 21 English chatbot responses as machine-generated, misclassified 18 as human-written and was indecisive on 2 (rank 5 of 5). Free version, tested 30 March to 2 April 2023.
- AIDI-S-0012Orenstrakh 20232023
Scored 82.46% on 114 human and 95.00% on 20 ChatGPT English coursework submissions through the authors' z-score wrapper, with 20 false positives in 114; the only tool whose accuracy on 10 QuillBot-paraphrased ChatGPT texts held at 100% (Tables 6, 8 and 9).
- AIDI-S-0018Pegoraro 20232023
Run as the Gehrmann et al. GLTR method: true positive rate 32.0% on ChatGPT responses and true negative rate 98.4% on human responses on a ChatGPT and human Q&A benchmark, March 2023 (Table I).
Two study records in the index covered GLTR on the morning of 9 November 2026, and a third was added later that day. The RAID benchmark (Dugan et al. 2024) ran GLTR with its repository default settings and reports a false positive rate on human-written documents of 100% at threshold 0.25, 99.3% at 0.5, 21.0% at 0.75 and 0.05% at 0.95, the highest rate at 0.5 of the 12 detectors tested alongside LLMDet at 96.0% (arXiv 2405.07940, Table 4, read 9 November 2026). The same paper names GLTR as the example of an open-source detector that "thresholding naively results in unacceptably high false positive rates".
Once the threshold is set to a 5% false positive rate, RAID 2024 reports GLTR at 89.8 accuracy on open chat models with greedy decoding and 0.5 on open non-chat models under sampling with a repetition penalty (Table 5), and 62.6 with no attack, 31.2 under synonym swap and 24.3 under homoglyphs (Table 6). The GLTR demo shows colours rather than a threshold, so the 99.3% describes the benchmark's default cut, not what a reader sees on screen.
Chaka 2023 ran the free GLTR demo on 21 English chatbot responses between 30 March and 2 April 2023 and reports 1 classified as machine-generated, 18 misclassified as human-written and 2 indecisive, the lowest of the five tools (rank 5 of 5) (DOI 10.37074/jalt.2023.6.2.12, read 9 November 2026). Other papers that name GLTR, among them Orenstrakh 2023, are not yet indexed here; their figures will appear on this card once each paper has its own record.
A third record, added 9 November 2026, is Orenstrakh 2023, which ran GLTR through the authors' z-score wrapper on 164 computing coursework submissions in April 2023 and reports 82.46% on 114 human and 95.00% on 20 ChatGPT English submissions by the threshold method, 20 false positives in 114, and the only unchanged result on 10 QuillBot-paraphrased ChatGPT texts, 100% before and after (arXiv 2307.07411, read 9 November 2026). That last figure places GLTR first in the robustness ranking, on a base of ten texts.
Pegoraro 2023, added 9 November 2026 as the fourth record, ran the Gehrmann et al. GLTR method among 20 detection methods on a ChatGPT and human question-and-answer benchmark in March 2023 and records a 32.0% true positive rate on ChatGPT responses and a 98.4% true negative rate on human responses, the highest true negative rate of the 20 (arXiv 2304.01487, Table I, read 9 November 2026); no ranking field takes a value from the printed rates.
Where GLTR appears in the index
Rankings
- AIDI-R-01AI detectors ranked by independent testing Two records added in the fifth wave on 9 November 2026, Pegoraro 2023 and Fleckenstein 2024, changed nine counts and none: Pegoraro 2023 tested ZeroGPT, GPTZero, Copyleaks, Originality.ai, Writer, Content at Scale (BrandWell), DetectGPT, the GPT-2 Output Detector and GLTR, lifting GPTZero to 12, the GPT-2 Output Detector to 10, Copyleaks to 7 and Originality.ai and ZeroGPT to 6; Fleckenstein 2024 tested 289 teachers and no software, so it counts for no card ([Fleckenstein 2024 record](/studies/fleckenstein-2024-teachers/)). Illuminarty, one of four cards added in the same wave, joined with its one image record from Ha and Passananti 2024, so 18 of 72 cards now qualify.
- AIDI-R-02AI detector false positive rates, ranked
- AIDI-R-08AI detectors ranked by published robustness to paraphrased and edited text
- AIDI-R-09AI detector false negative rates, ranked
- AIDI-R-11AI detectors ranked by named integration surfaces
- AIDI-R-17AI detectors ranked by the generator models the vendor names
- AIDI-R-18AI detectors ranked by study records on non-English and non-native text
- AIDI-R-20AI detectors ranked by launch year, with every change of hands and withdrawal the cards record
GLTR qualifies for two of the five launch rankings and three of the five added on 9 November 2026. In AI detectors ranked by independent testing the card counts 3 study records, and in AI detector false positive rates the card ranks on the RAID 2024 figure of 99.3% at threshold 0.5, the highest figure in that ranking (detectors.json, read 9 November 2026). GLTR has no free allowance stated in words and no language list, so the free tier and language rankings leave the card out.
Since 9 November 2026 GLTR also ranks first in robustness to paraphrase on 10 of 10 QuillBot-paraphrased texts in Orenstrakh 2023, last in false negative rate on 18 of 21 chatbot responses labelled human in Chaka 2023, and is listed in the false positive evidence review.
No audience view lists GLTR, because the card states no API documentation beyond the local server, no integrations and no plans. Two feature slices do: the open-source view carries the repository, its Apache License 2.0 and the last commit of 27 June 2023, and the published false positive rate view carries the RAID 2024 figure; the question page on how AI detectors work places GLTR as the one zero-shot statistical display in the index. The card sits on the register of every AI detector tracked here with the fields it does carry: modality, generators, free access, the paper's claim and one study.
Questions about GLTR AI detector
Is GLTR free to use?
Yes. The demo at demo.gltr.io needs no account and the code is on GitHub under the Apache License 2.0, read 9 November 2026. There is no paid plan and no vendor.
What model does GLTR use to detect AI text?
GPT-2 117M, per the project page read 9 November 2026, with BERT available as an alternative backend in the repository. Each word is coloured by its rank among GPT-2's predictions: top 10 green, top 100 yellow, top 1,000 red, the rest purple.
How accurate is GLTR?
The paper reports that the overlay raised human detection from 54% to 72% in a 35-student study and gives an AUC of 0.87 for its top-k features, read 9 November 2026. RAID 2024 reports a 99.3% false positive rate at threshold 0.5 and 89.8 accuracy at a fixed 5% false positive rate on open chat models with greedy decoding.
Does GLTR work on ChatGPT or GPT-4 text?
The project page and paper make no claim about models after GPT-2, read 9 November 2026. RAID 2024 tested GLTR on 11 generators including GPT-4 and reports the figures above at a 5% false positive operating point.
Sources and revisions
Sources
- gltr.ioRead 9 November 2026
- github.com/HendrikStrobelt/detecting-fake...Read 9 November 2026
- arxiv.org/abs/1906.04043Read 9 November 2026
- arxiv.org/pdf/2405.07940Read 9 November 2026
- doi.org/10.37074/jalt.2023.6.2.12Read 9 November 2026
Revision log
- Card created
- Chaka 2023 record added, 2 study records
- Orenstrakh 2023 record added, 3 study records
- Links to the open-source and published false positive rate views and the detection methods question added2026-11-09: pegoraro 2023 record added to the study list in the fifth wave
). Illuminarty, one of four cards added in the same wave, joined with its one image record from Ha and Passananti 2024, so 18 of 72 cards now qualify.: register plate](/img/independently-tested-480.webp)